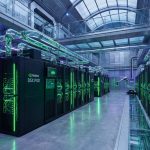

Artificial intelligence depends on more than software. Large AI models require computing infrastructure capable of processing enormous amounts of information efficiently.
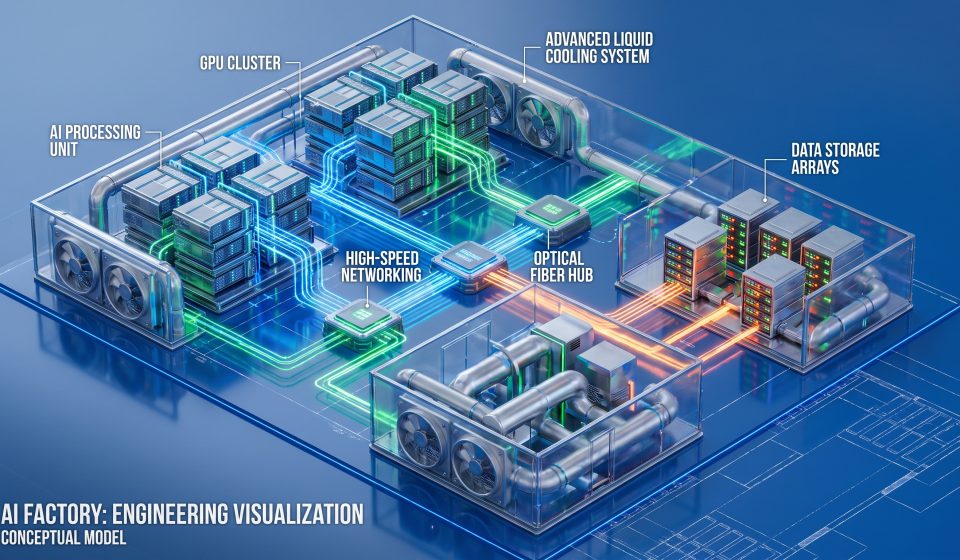
The term AI factory describes an environment built to support these workloads at scale.
As NVIDIA introduces modular infrastructure concepts such as DSX POD, understanding the components of an AI factory becomes increasingly useful for IT professionals and technology enthusiasts.
What Makes an AI Factory Different?
Traditional data centers support many kinds of workloads, including websites, databases, email, and business applications.
AI factories are designed around the demanding requirements of AI training and inference.
These workloads can involve large numbers of accelerators exchanging data at high speeds while consuming substantial electrical power.
1. GPUs and AI Accelerators
Graphics processing units and other AI accelerators perform large numbers of mathematical operations in parallel.
This makes them useful for the matrix computations common in machine learning.
Different accelerators have different memory capacities, processing capabilities, power requirements, and supported software ecosystems.
Choosing hardware requires evaluating the actual workload rather than assuming the most expensive processor is always the best option.
2. High-Speed Networking
Large AI systems often distribute work across many processors.
Those processors need to exchange information quickly, making networking a critical performance factor.
Insufficient network capacity can leave expensive computing hardware waiting for data.
AI infrastructure therefore relies on carefully designed connections, switches, and communication software.
3. Storage Infrastructure
AI workloads can require large datasets, model checkpoints, logs, and other files.
Storage systems must provide sufficient capacity and appropriate performance.
Different workloads may require different balances of throughput, latency, durability, and cost.
Fast storage alone is not enough if networking or software creates a bottleneck.
4. Electrical Power
Large AI facilities require dependable power delivery.
Electrical planning includes capacity, distribution, redundancy, and operational efficiency.
Power availability can influence the location, scale, and deployment schedule of an AI project.
5. Cooling Systems
Computing equipment produces heat during operation.
Cooling systems help maintain appropriate temperatures and support reliable performance.
High-density AI equipment can require advanced thermal management, including liquid-cooling approaches in suitable deployments.
Cooling choices depend on hardware density, site conditions, maintenance capabilities, and engineering requirements.
6. Software and Orchestration
Hardware must be coordinated through operating systems, drivers, networking software, workload schedulers, and management tools.
These systems help allocate computing resources, monitor performance, and recover from failures.
Without effective software management, a large collection of processors may operate inefficiently.
7. Reliability and Maintenance
AI infrastructure needs monitoring, maintenance, and fault management.
Operators must detect hardware failures, manage updates, protect data, and maintain operational continuity.
These requirements become more complex as infrastructure scales.
How Does NVIDIA DSX POD Fit In?
NVIDIA DSX POD aims to standardize aspects of large-scale AI infrastructure deployment.
Its modular approach emphasizes coordinated systems and factory-based integration.
Read our NVIDIA DSX POD guide for the October 2026 announcement and its implications.
What Does This Mean for Smaller Businesses?
Most organizations do not need to operate a large AI factory.
They may use cloud-based AI services, smaller local servers, or workstations suited to their workloads.
The same general principles still matter: computing capacity, memory, storage, network performance, security, and operating costs should be considered together.
Choosing Hardware for AI Workloads
Organizations should begin by identifying the applications they need to run.
Model size, expected users, response-time requirements, data sensitivity, and budget all influence the right infrastructure approach.
Readers researching computing equipment can explore Aztek Computers for relevant hardware categories and product information.
Verify specifications and compatibility before purchasing equipment for specialized AI workloads.
Final Thoughts
AI factories combine computing hardware with networking, storage, power, cooling, and management software.
Successful infrastructure design depends on how these components work together rather than on processor performance alone.
Modular approaches such as NVIDIA DSX POD reflect efforts to make large deployments more repeatable and predictable.
Frequently Asked Questions
What is the purpose of an AI factory?
It provides infrastructure for performing AI workloads such as model training and inference at scale.
Why do AI factories need GPUs?
GPUs and similar accelerators are efficient at many of the parallel mathematical operations used in machine learning.
Why is networking important?
Distributed AI workloads require processors to exchange data quickly and reliably.
Do AI factories use liquid cooling?
Some high-density deployments use liquid cooling, but cooling requirements vary by hardware and facility.
Can small businesses run AI without an AI factory?
Yes. Many businesses use cloud AI services, workstations, or smaller servers instead.